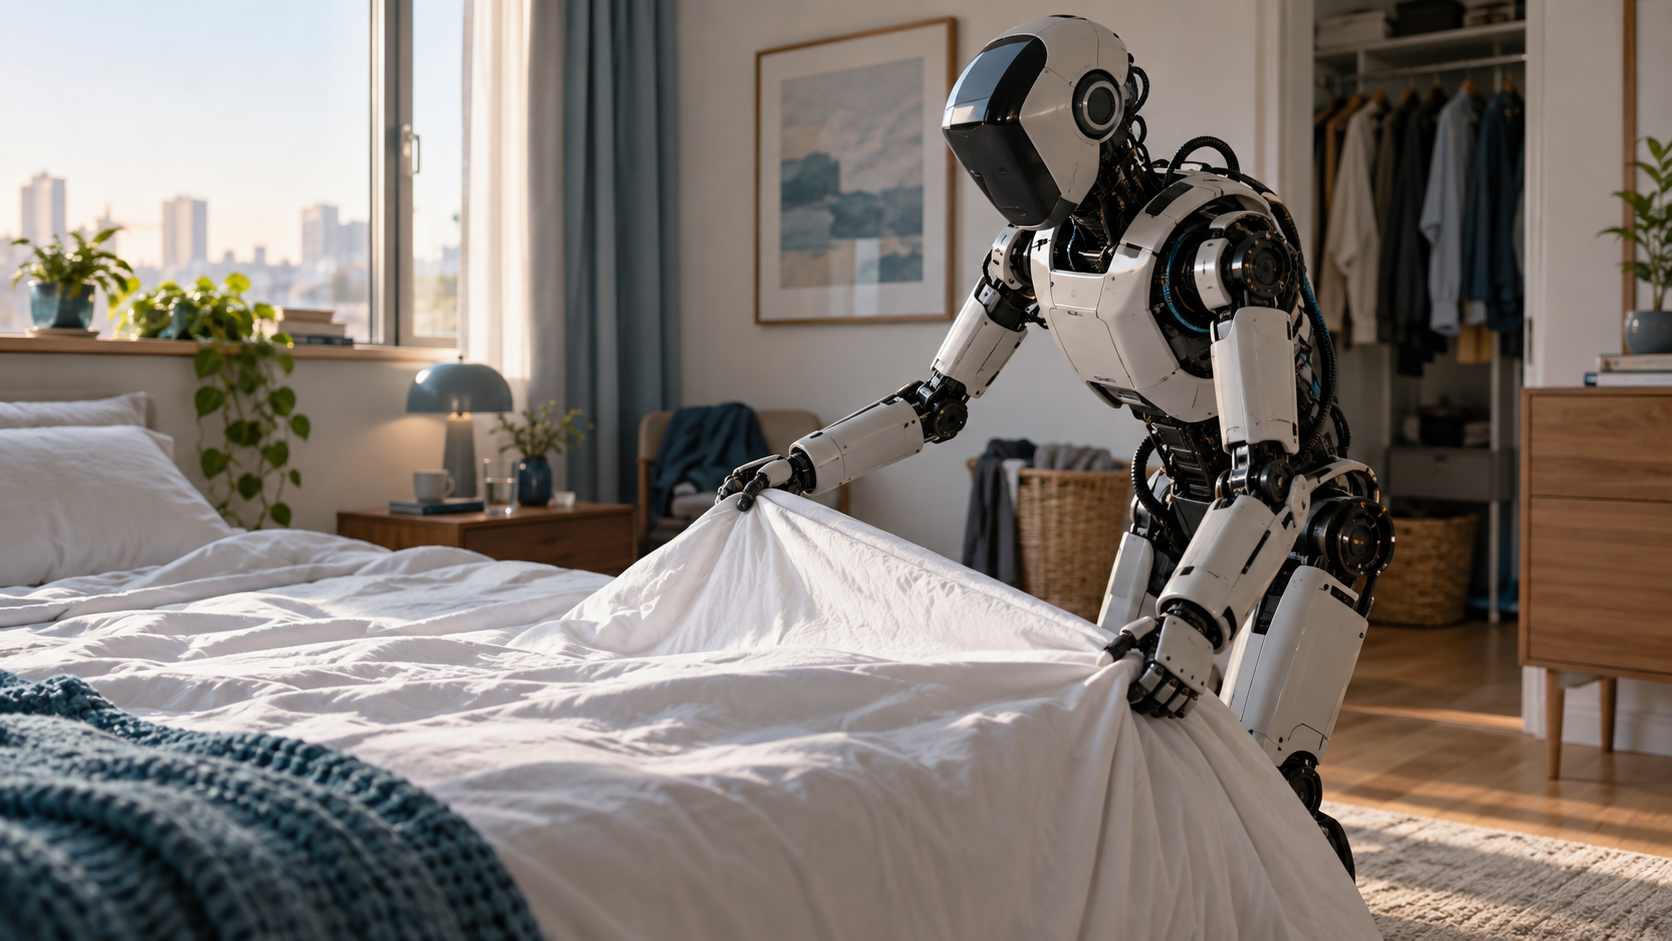
A humanoid walks into a home it has never seen, crosses a cramped bedroom and starts making the bed. That is the attention-grabbing image behind Figure’s Helix 2.5 demonstration. The more important story is what happened before the robot entered the room: it had learned broad patterns of human activity from video, then transferred that experience into physical action.
Figure says it evaluated the new model across 30 previously unseen homes in the San Francisco Bay Area. The robot was asked to tidy living rooms, fold towels and make beds without collecting training data inside those apartments. In Figure’s aggregate evaluation, a policy initialized with the company’s Index pretraining succeeded in 56 percent of zero-shot trials. The comparable model trained from scratch reached only 9 percent.
The YouTube Short that prompted this article focuses on the most visually immediate part of the test: bed-making. It reports that the robot completed that task in roughly two out of three trials, while living-room tidying remained much less reliable. Those task-level figures come from a summary of Figure’s company demonstration, not from an independent laboratory replication. That distinction matters, because the result is promising without proving that a household robot is ready for unsupervised daily use.
In this article
Why an unfamiliar bedroom is a serious robotics test
Making a bed sounds simple because people solve it almost automatically. For a robot, it combines several difficult problems. It must recognise deformable fabric, locate corners that may be hidden in folds, coordinate both hands, manage contact forces and reposition its entire body around furniture. The same movement cannot simply be replayed: bed heights, mattress sizes, room layouts, pillows and comforters vary.
That variation is the real subject of the Helix 2.5 experiment. Most impressive robot videos are recorded in carefully prepared spaces, often after data has been collected in the same environment. A policy can become highly capable inside one familiar setup and still fail when a table is ten centimetres higher or a blanket behaves differently. Figure deliberately moved the evaluation into rented, lived-in homes that were not arranged around the machine.
According to the company, no data from the evaluation homes, objects or rollouts was used to adapt the model or select its checkpoint. The tasks themselves were not unknown: Figure had fine-tuned three behaviours using task-specific data collected elsewhere. “Zero-shot” therefore applies to the rooms and manipulated objects, not to a robot inventing an entirely new chore from a verbal request.
What Helix 2.5 was asked to do
The evaluation covered three long-horizon behaviours. For living-room tidying, the robot had to collect every one of 13 to 15 scattered toys and put them into a basket. For towel folding, every towel had to be picked up, folded and placed in a basket. For bed-making, both pillows and the corners of the comforter had to reach the top of the bed, with the comforter pulled smooth.
Figure awarded no partial credit in its headline success metric. A nearly completed room with one toy left on the floor still counted as a failed trial. Timeouts or human intervention for safety also meant failure. This strict definition makes the 56 percent aggregate result more meaningful than a highlight reel, but it also exposes the present limit: about 44 percent of complete trials still failed under the company’s own criteria.
The robot sometimes displayed a useful capability that is hard to capture in a single percentage: self-correction. Figure’s footage shows it stepping back, changing its stance and moving around a bed to recover from a poor fold. Long household tasks rarely fail because of one dramatic error; they break down through small misalignments that accumulate. A system that can recognise lost progress and reposition itself is more valuable than one that only performs a polished motion when every object begins in the expected place.
The real bet: learning robot skills from human video
Helix 2.5 was pretrained on Index, Figure’s proprietary dataset of human behaviour. The company says contributors in more than 100 countries have uploaded over 16 million videos from homes and workplaces. The collection includes cooking, cleaning, laundry, retail and logistics. Figure says it filters, reviews, deduplicates, rebalances and captions that stream for training.
This approach addresses a central bottleneck in robotics. Robot demonstrations are expensive: a machine, a suitable space, an operator and supervision are usually required for every hour of data. Human video is vastly easier to collect and contains much more environmental diversity. A model can see hundreds of ways to handle a towel or approach a bed before a humanoid performs the movement itself.
But human video does not directly provide motor commands, joint angles or reliable force information. Human bodies and robot bodies also differ. Transferring visual experience into safe robot action is therefore not a simple imitation exercise. Helix 2.5 matters because Figure’s controlled comparison suggests that broad human-video pretraining supplied useful physical priors: with architecture, task data, optimisation and evaluation held constant, success rose from 9 to 56 percent.
Figure also reports predictable improvement as Index grew. Four models were trained on nested datasets spanning an eightfold range, and their robot-action prediction loss fell smoothly enough to forecast the largest run from smaller ones. The internal result supports an idea familiar from language models: pretrain broadly, specify a task with less specialised data, then generalise.
Why 56 percent is both impressive and insufficient
A robot that succeeds in more than half of strict, full-task trials across unfamiliar homes is a notable research result. It is not a product-readiness threshold. In a home, a single failed attempt may leave a heavy object misplaced, bedding on the floor or a robot blocked in a walkway. Consumers will judge reliability over hundreds of chores, not a curated set of three.
The demonstration also leaves important questions unanswered. Figure has not supplied an independent audit of the trial protocol or a public dataset that would allow another laboratory to reproduce the result. The evaluation does not establish long-term hardware reliability, child and pet safety, privacy protections for cameras operating inside homes, recovery from completely novel requests, operating cost or useful task speed compared with a person.
Thirty real apartments offer more diversity than one lab, but remain a small slice of housing worldwide. Stairs, narrow doorways, poor lighting, clutter, unusual furniture and moving people or animals could alter performance sharply. The next credible milestone is broader evaluation with transparent denominators and third-party scrutiny.
The Alpha Bionic view
The bed is the perfect visual hook, but the foundation model is the real news. Helix 2.5 suggests that humanoid robotics may be moving away from teaching one machine one task in one place. If experience captured from people can reduce the amount of robot-specific training, developers gain access to a far larger and more varied learning source.
That does not mean general household robots have arrived. A 56 percent success rate is still too low for autonomous service, and all central performance claims currently come from Figure. Yet the gap between 9 and 56 percent is large enough to take seriously. It indicates that the path toward useful home robots may depend less on scripting every movement and more on building models that understand how physical work varies from room to room.
The strongest conclusion is therefore narrower than the viral image and more consequential: Helix 2.5 did not prove that a humanoid can run a household. It offered evidence that human experience can help a robot act in places where it has never trained. If independent tests confirm that transfer, the robot making a bed will be remembered not as a domestic novelty, but as an early sign that physical AI is beginning to travel.
Sources
- Figure: “Helix 2.5: Zero-Shot 30-Home Generalization”, September 17, 2026
- Figure: “Introducing Index: Building The World’s Largest and Most Diverse Physical Dataset”, August 25, 2026
- Figure: “Helix 2.5 30-Home Generalization” video, September 2026
- NORDVIND AI: German video summary supplied as the article prompt, September 18, 2026