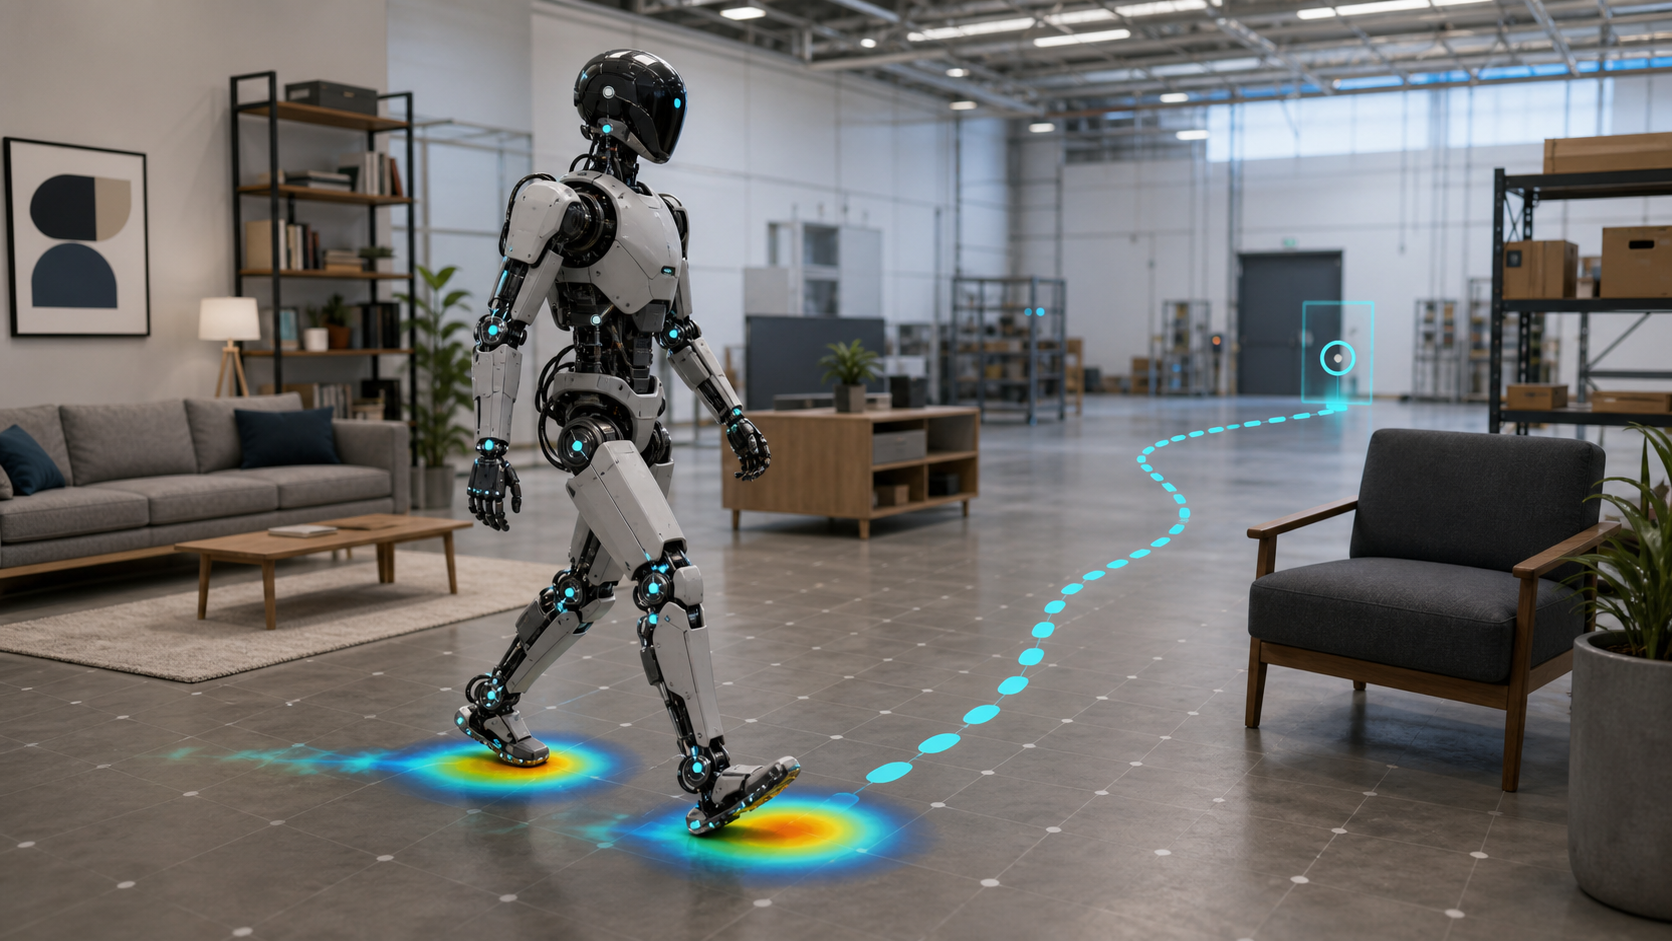
A humanoid can look convincing in a ten-second video and still fail the moment its feet slide, a contact arrives too early or a spoken instruction sends it around the wrong chair.
Two robotics benchmarks released on 13 August 2026 are designed to expose precisely that gap. HumanTracker evaluates whether tracked humanoid motion agrees with human perception, including the physical artifacts that ordinary pose errors can overlook. HumanoidVLN tests whether robots of different sizes can follow language instructions while obeying the realities of bipedal movement.
The result is a useful correction to the demo culture surrounding humanoid robots: motion quality and task reliability need measurements that are harder to edit than a highlight reel.
In this article
The key points
- HumanTracker includes about 153 hours of optical motion trajectories from professional performers.
- Its HumanScore metric was trained on 12,000 comparison pairs containing 24,000 motions.
- The benchmark targets failures such as unstable support, foot skating and incorrectly timed contacts.
- HumanoidVLN evaluates four navigation models across four humanoid embodiments and 933 collision-aware reference episodes.
- The best reported mean navigation success rate was 43.55 percent, highlighting substantial room for improvement.
Why conventional motion scores can miss an obvious failure
Robot motion tracking is often evaluated by averaging differences between a reference pose and the robot’s pose frame by frame. Such numbers are useful, but an average can hide what viewers notice immediately.
A foot may slide across the floor while the body roughly matches the target posture. A heel may touch down too early. The robot may appear to float for a fraction of a second or shift its weight onto a leg that is not providing stable support. Each pose can be numerically close to the reference while the full movement still looks physically wrong.
This matters beyond aesthetics. Incorrect contact can make a robot less stable, increase energy use and turn a small tracking error into a fall when the machine carries a load or meets an uneven surface.
HumanTracker asks people what looks right
The HumanTracker project combines a much larger motion collection with a preference-aligned score. Its roughly 153 hours of optical trajectories come from multiple professional performers and are organized into four motion families with text labels for diagnosis.
HumanScore is trained on 12,000 motion pairs covering 24,000 motions. Instead of treating every joint deviation as equally meaningful, it aims to better predict which result a human observer considers physically convincing. In the authors’ evaluation, it revealed contact and stability failures that standard kinematic measures often missed.
The benchmark does not make a humanoid move better by itself. It changes the scoreboard. That can influence research because teams optimize what their tests reward. If the metric penalizes sliding feet and mistimed contact, control systems have a stronger incentive to solve those problems rather than merely reduce average pose error.
Following language is harder when the camera walks
HumanoidVLN tackles a different weakness. Vision-language navigation systems are commonly tested with wheeled or simplified agents. A humanoid introduces body-specific constraints: it must balance, turn through feasible steps and process camera images that bounce and rotate with its gait.
The benchmark uses NVIDIA Isaac Sim and supports several body configurations. The paper reports results for Unitree G1, Unitree H1 and two internal humanoids ranging from 1.17 to 1.80 meters in height. Four navigation approaches were tested across 933 reference episodes in large reconstructed or artist-designed environments.
The leading model in the reported comparison, JanusVLN, achieved a mean success rate of 43.55 percent. That figure should not be read as a universal score for humanoid navigation. It applies to this benchmark, its tasks and its evaluation setup. It nevertheless demonstrates that language-guided movement across bodies remains far from solved.
A small bridge from simulation to a real Unitree G1
The researchers also ran a 20-episode pilot using DualVLN and a physical Unitree G1. They report a strong correlation between simulation and real-world navigation errors, along with a mean absolute difference of 0.68 meters.
That is encouraging for the benchmark’s usefulness, but 20 episodes are too few for broad conclusions. Different lighting, floor friction, crowds, moving objects and sensor degradation can expose gaps that a controlled pilot does not contain.
What these tests reveal about humanoid demos
A polished demonstration usually answers a narrow question: did the robot complete this visible sequence at least once? A benchmark should ask harder questions. Does performance hold across many motions, rooms, instructions and body types? Are failures counted consistently? Can another team reproduce the evaluation?
HumanTracker and HumanoidVLN focus on complementary layers. One examines the physical credibility of the body. The other examines whether perception, language, planning and locomotion work together. A commercially useful humanoid needs both.
What to look for in the next robot video
- Watch the feet: do they stay planted when the body transfers weight?
- Look for cuts immediately before difficult contact or turns.
- Ask whether the route and instruction were chosen in advance.
- Check whether failures and retries are reported, not only the successful run.
- Separate simulated results, teleoperation and fully autonomous execution.
Bottom line
Humanoid robotics does not lack spectacular videos. It lacks enough shared tests that make physically implausible motion and navigation failures impossible to hide.
These two benchmarks do not settle which humanoid is best. They offer something more valuable at this stage: clearer ways to measure the distance between a robot that resembles a person and one that can move reliably through a human world.
Sources
- HumanTracker, submitted 13 August 2026 and accepted to ECCV 2026
- HumanoidVLN, submitted 13 August 2026